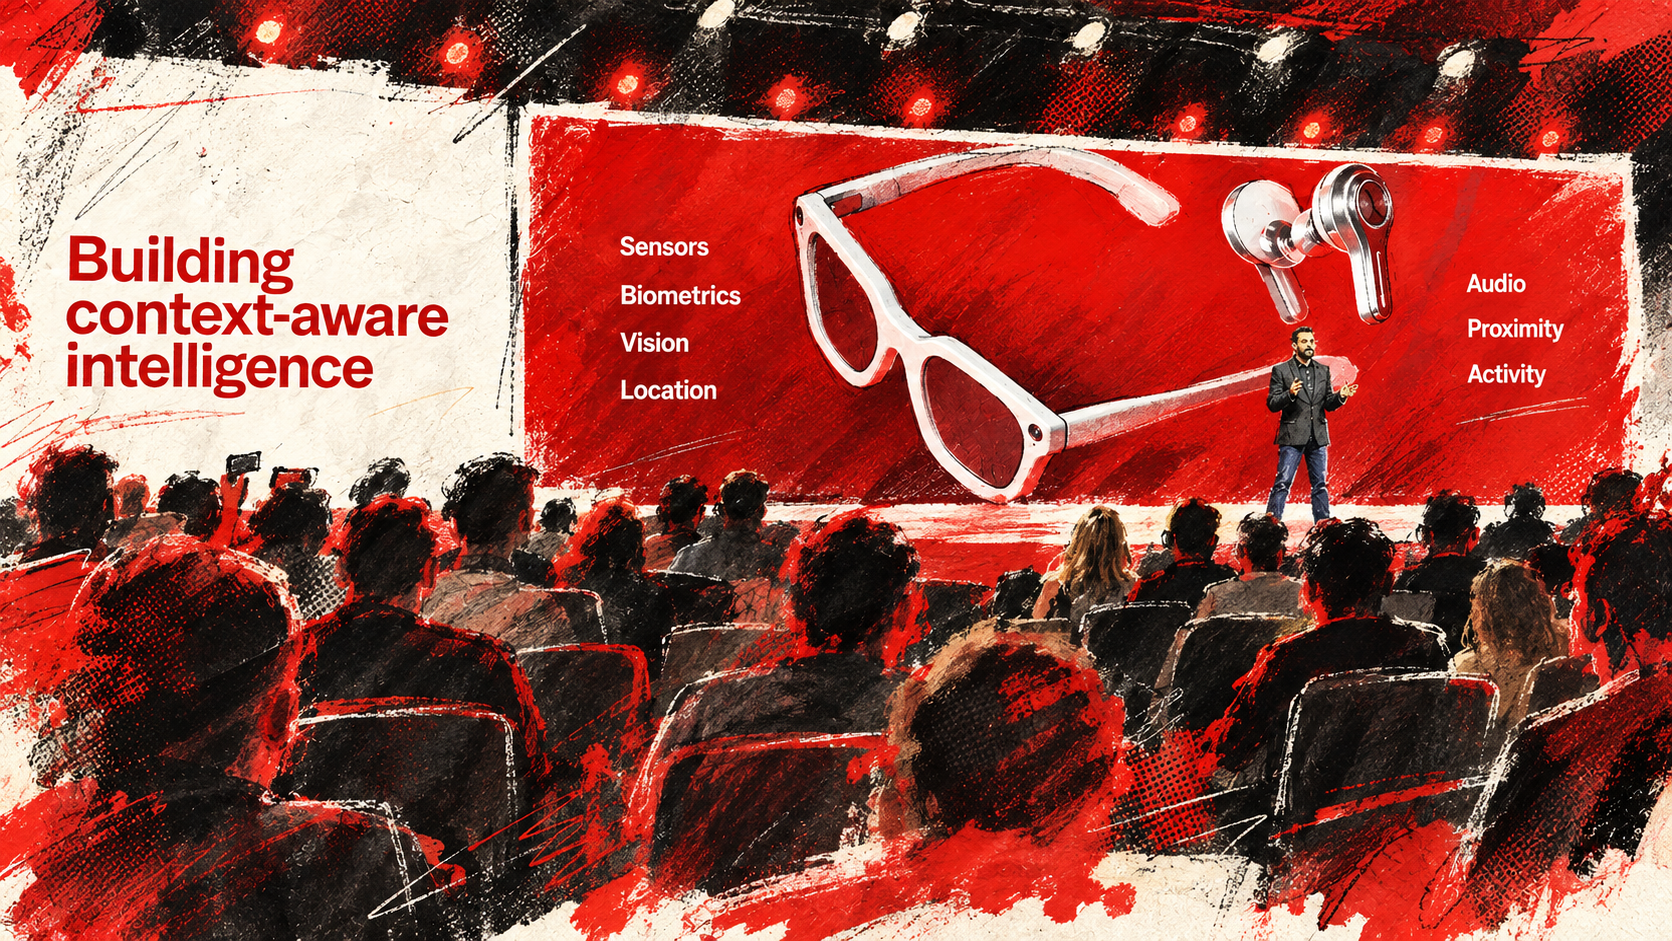
uring Qualcomm's Snapdragon Summit, one number made me snap my head up: support for 30-billion-parameter Mixture-of-Experts (MoE) AI models running locally on mobile devices.
Qualcomm claims its most advanced chipset yet, the Snapdragon 8 Elite Extreme Gen 6, can pull this off. For context, the largest on-device model I'd seen on a phone was around 4 billion parameters, running on top-tier chips like Apple's A20 Pro. To see how a more than sevenfold jump is possible, it helps to understand how an MoE model works, because it's different from a traditional, or dense, model.
"Very smart AI architects here have moved to this mixture of expert models, so you can get something that's sort of equivalent in kind of capability from a single dense model into actually what's composed of multiple small models," Chris Patrick, SVP and General Manager of Handsets at Qualcomm, told The Deep View.
Qualcomm goes a step further by storing some of those experts in flash storage rather than keeping them all in RAM at once. As Patrick put it, "the memory furniture on a phone" isn't big enough to hold 30 billion parameters. Instead, the system predicts which expert it will need for the next token or action, loads it into memory, runs it, and then swaps it out for the next one.
This isn't to say dense models are obsolete. Smaller 4-billion-parameter models are already capable of a lot, from answering questions and summarizing documents to understanding images and carrying out tasks within apps, and their speed and efficiency make them ideal for everyday requests. But when a task calls for more advanced reasoning, users can now tap into far larger models than a phone's hardware would otherwise allow.
"In the end, it is trying to approximate what you'd have for a single big dense model that might require 32GB of RAM on the phone," added Patrick. (Today's top-end phones typically have 12GB to 16GB of RAM.)
So can any model be run in the mixture of expert architecture? Not quite. The model itself has to be built in that specific format, but the good news is that MoE now underpins many of today's most capable open models, from DeepSeek's V4 series and Moonshot AI's Kimi K2.6 to Alibaba's Qwen3.6-35B-A3B, which, at 35 billion total parameters with only about 3 billion active at a time, is close to the scale Qualcomm says its new chip can handle. Google has also explicitly disclosed its use of MoE architectures, and it's worth noting that proprietary frontier models from OpenAI and Anthropic are widely believed to use MoE-style architectures, but they generally don't disclose architectural details.
Our Deeper View
Raw intelligence is no longer the bottleneck. Models keep getting more capable as more is demanded of them, especially with the rise of agentic AI. The real challenge, as noted above, is running these models on the devices we carry every day, like smartphones, smartwatches, and eventually smart glasses, which are the devices that will truly bring the vision of personal AI to life. That's why the industry is pursuing so many ways to make models not just smaller but more efficient, from model routing, which has surged in popularity, to domain-specific models built for particular tasks. MoE feels like a natural evolution of both: a single model made up of specialized experts, activated only when needed, that together deliver the capability of a much larger model.
Disclaimer: Sabrina Ortiz's travel to Snapdragon Summit was paid for by Qualcomm. The Deep View's coverage is editorially independent from the companies we cover.